Interpretation, Drift & Cognitive Continuity — Essay 1 of 7
Data as Representation of Truth
Why AI governance requires continuity of interpretation
Also essay 10 of the Backbone Narrative. This essay bridges two series — read as essay 1 here in Interpretation, Drift & Cognitive Continuity, or as essay 10 of the Backbone Narrative, continuing from Civilisational Decay and the Invisible Opportunity Cost and leading into The Horizon of Reconstruction Bankruptcy.
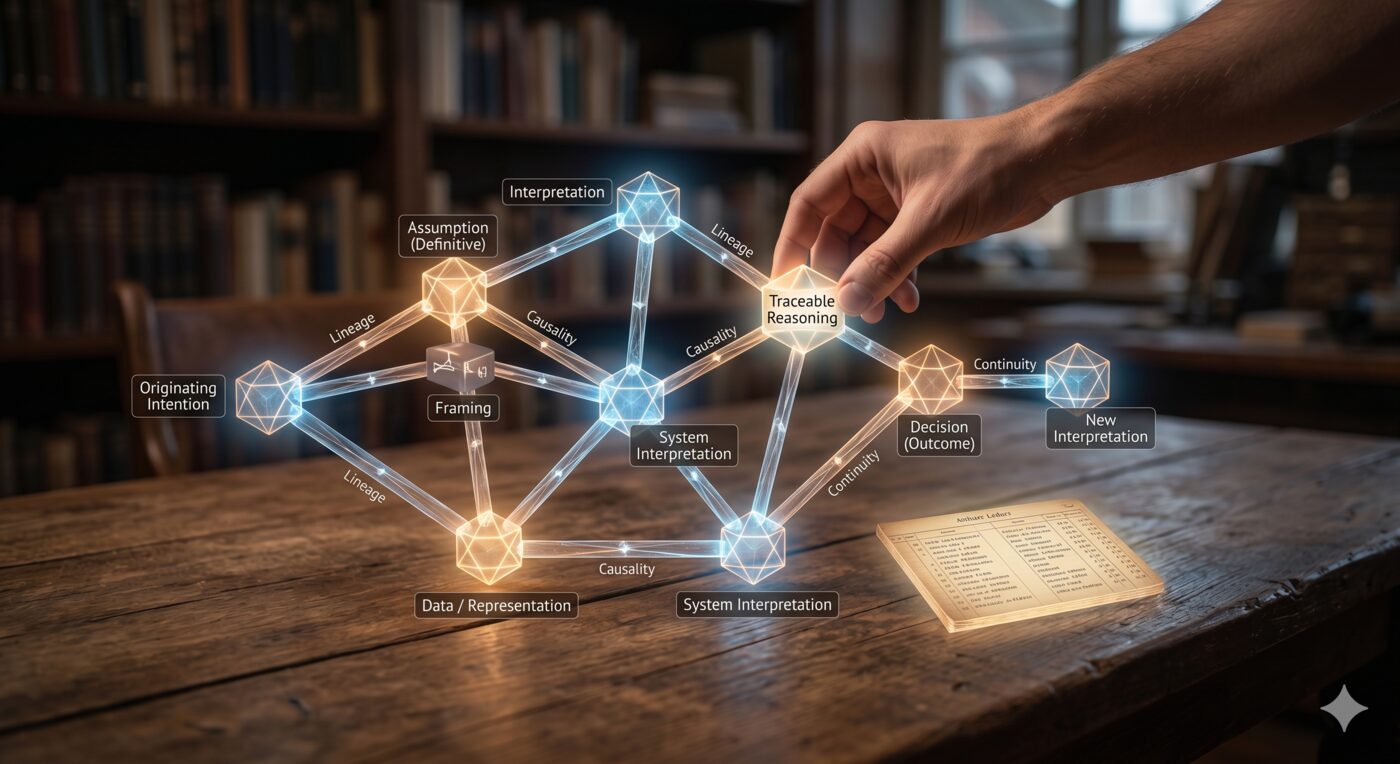
Philosophers and scientists have wrestled for centuries with the distinction between measurements and the reality those measurements describe — from Korzybski's observation that the map is not the territory, to Heraclitus noting that no one steps in the same river twice. Symbols have never been the things they represent.
AI is scaling that old friction to a civilizational level, under a dangerous working assumption: that a sufficiently large, sufficiently optimized dataset will eventually converge on truth. It won't, because data was never truth to begin with. Data is interpreted reality — compressed context, structured determination, representation situated in a particular history. That distinction matters enormously, because AI systems increasingly operate not on reality itself but on layers of accumulated representation. The governance question that actually matters isn't where the data came from or how much of it exists. It's what interpretation produced it.
The Hidden Assumption Behind "Better Data"
Much of the current discourse around AI quietly assumes that more accurate data leads to more accurate models, which leads to more truthful systems — treating data as if it were objective, context-free, directly representative of reality. But no meaningful dataset exists without framing, selection, categorization, and interpretation built into it from the start. Data is never raw reality. It's already transformed understanding, carrying embedded assumptions about what mattered, what was measured, what got ignored, and how the categories inside it were defined in the first place.
Data doesn't eliminate interpretation. It transports interpretation, preserving a symbolic representation across time while the meaning behind that representation becomes steadily harder to reconstruct. As AI systems scale, they inherit historical assumptions, institutional framings, and prior determinations without necessarily preserving the reasoning that produced them.
Two Ordinary Examples
A medical dataset looks objective on its surface — symptoms, diagnoses, treatments, outcomes. But embedded within it are assumptions about what counts as illness, how symptoms get interpreted, which populations were actually represented, and which diagnostic standards happened to be institutionalized at the time. The data isn't neutral. It's institutionalized interpretation encoded as structure.
Economic indicators — GDP, productivity, unemployment, inflation — look even more factual, and depend just as entirely on definitional boundaries, valuation assumptions, and political choices about what to measure in the first place. Even "growth" is interpreted through cultural priorities and institutional incentives before it ever becomes a number. What the data reflects is what the system decided, at some point, to treat as meaningful.
How AI Scales the Problem
AI systems amplify this because they aggregate representations, compress interpretations, and generalize patterns across domains that were never actually connected to begin with. The result is that AI systems increasingly operate on accumulated interpretation layers rather than anything resembling direct access to reality — which creates a genuinely dangerous misconception: that controlling the data means controlling the truth. Interpretation stays structurally embedded in collection, labeling, and categorization no matter how tightly the data itself is controlled afterward.
Why This Matters for Governance
Most current governance frameworks focus on data quality, provenance, bias reduction, and compliance. These matter, but they tend to skip past interpretive continuity entirely. Without it, systems can't be meaningfully audited, disagreements can't be reconstructed, and assumptions can't be revisited. The real question isn't only whether the data was correct. It's what interpretation actually produced it.
Human institutions already understand this, even if AI governance hasn't caught up yet. Courts don't just inspect facts — they reconstruct interpretation, intention, and admissibility. Auditors don't just inspect numbers — they reconstruct assumptions and lineage. Science itself depends on reproducibility and contestable reasoning, not just correct results. Civilization already runs on governed interpretation. AI systems are now scaling interpretation faster than these traditional institutions were ever built to reconstruct it.
What Continuity of Interpretation Actually Requires
The belief that better data solves alignment on its own fails for a specific reason: interpretation stays distributed, meaning stays contextual, and representations stay incomplete no matter how much data accumulates. Two systems can process identical data and still reach incompatible conclusions, because their underlying assumptions, objectives, or continuity of interpretation diverged somewhere upstream. That's why structural alignment can't rest on output control or dataset scaling alone — it needs decision lineage, interpretive continuity, and genuine reasoning traceability, or systems end up operationally capable while remaining epistemically opaque.
Data, in this light, is better understood as representation infrastructure carrying historical interpretation forward, not as truth in itself. That reframes what governance actually has to track: how representations were produced, how interpretations shifted over time, and whether the continuity of meaning behind them remains reconstructable at all. As AI systems become more distributed and autonomous, the real question stops being simply "can we verify the outputs" and becomes "can we reconstruct the interpretation that produced them." Without that, oversight becomes purely forensic — arriving after the fact rather than functioning as real governance.
This is, ultimately, a civilizational-scale version of a very old problem. Law, science, education, and finance all depend on reconstructable reasoning, generation after generation. What a society calls knowledge is really just interpretation that has been stabilized enough to persist across time. Without continuity of interpretation, understanding fragments and institutions drift — reconstructing, at real cost, what they failed to preserve in the first place.
The information superhighway solved distribution: moving data further, faster, at greater scale. Distributed AI-mediated cognition introduces a different problem entirely — preserving coherent understanding across interpretation that's now spread across many systems and actors at once. The question worth asking is no longer just whether a system can produce an answer. It's whether civilization can still reconstruct the interpretation that produced it.
The map was never the territory. The data was never the truth. What survives is whatever interpretation we manage to keep reconstructable.
— Arne Mayoh
Declaration of Generative AI and AI-Assisted Technologies
This essay was developed with the assistance of AI systems as a research and editorial tool, for drafting support and structural revision. The argument and conclusions are the author's own.
Essay 1 of the Interpretation, Drift & Cognitive Continuity series.